Ask a modern AI model to read a scanned invoice, find the dent in a photo of a car door, or tell you when the forklift first appears in a two-hour warehouse video, and there is a good chance it will manage. That everyday trick is the work of vision-language models, or VLMs: systems that take pictures and words in together and answer in words. By late 2026 the field has split into a crowded open-weight camp and a handful of frontier cloud services, with specialist vision encoders quietly powering much of both. This guide explains how VLMs work, compares ten leading options in one capability matrix, and offers a practical way to choose.
What a VLM is, and how it works
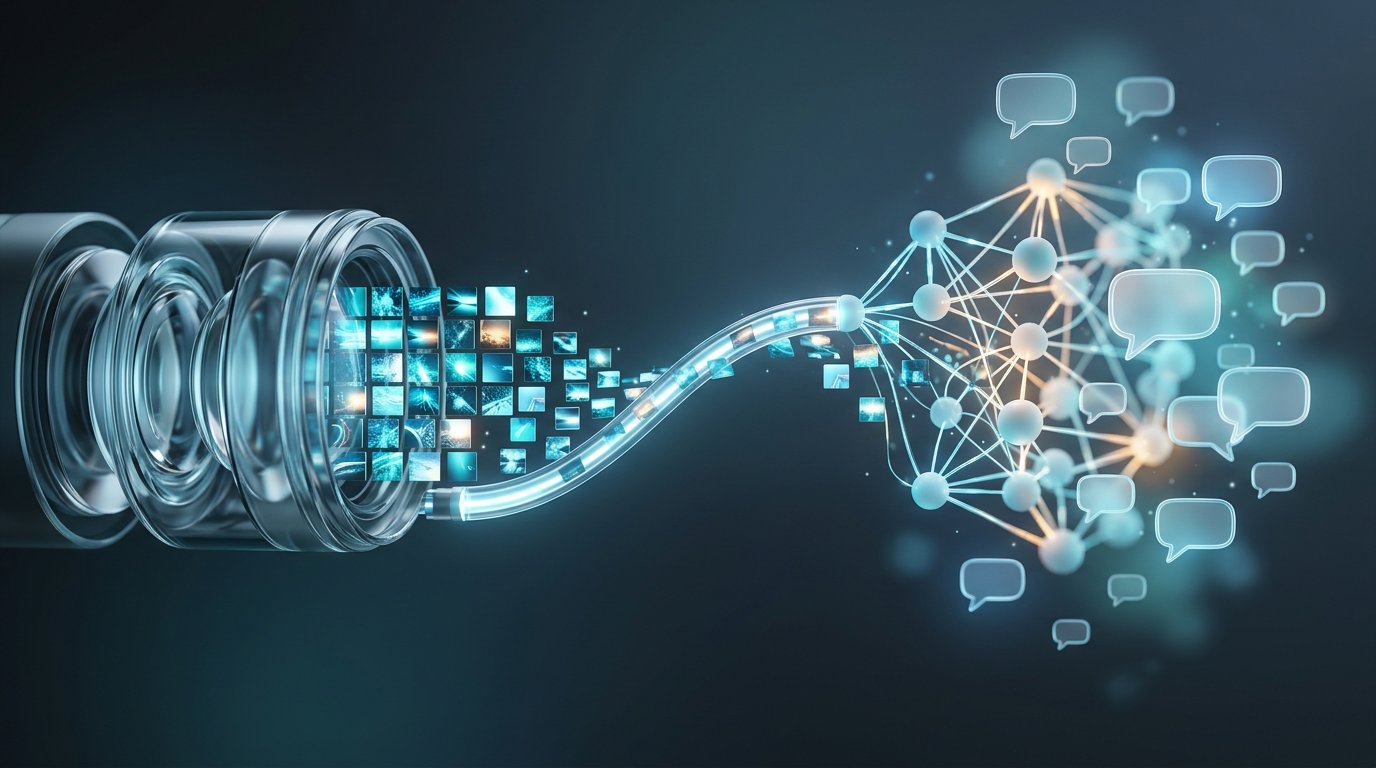
Most VLMs are built from three parts. A vision encoder chops an image into small patches and turns each patch into a vector of numbers. A projector, often a small multilayer perceptron (MLP), translates those vectors into the same “language” the text model uses. Then a large language model reads the projected image tokens alongside your prompt and writes the answer. The InternVL team names this recipe directly: its InternVL3.5 models “follow the ViT, MLP, LLM paradigm,” pairing InternViT encoders with Qwen3 and GPT-OSS language models, according to the InternVL3.5 model card.
Variations are multiplying. Google’s PaliGemma 2 joins a SigLIP-So400m image encoder to Gemma 2 decoders. Meta describes Llama 4 as natively multimodal with “early fusion,” so image and text tokens share one mixture-of-experts backbone from the start. And Google’s newest twist removes the encoder entirely: the Gemma 4 model card says the 12B “Unified” model projects raw image patches and audio straight into the language model “through lightweight linear layers,” which the company says cuts multimodal latency and lets the whole model be fine-tuned in one pass.
Image resolution is the hidden cost lever. Gemma 4 lets developers set a visual token budget of 70, 140, 280, 560 or 1,120 tokens per image, recommending low budgets for captioning and video and high budgets for OCR and small text. InternVL3.5 represents each image tile with 1,024 encoder tokens, compresses them to 256 for the language model, and its Flash variants route simple patches down to 64 tokens, cutting visual tokens by half while keeping “nearly 100%” of performance, per OpenGVLab.
Where DINO fits: the encoder, not the chatbot
Meta’s DINO family belongs in this conversation, but in a different seat. DINOv3, released in August 2025, is a self-supervised vision backbone trained on 1.7 billion images without labels and scaled to a 7-billion-parameter model. It produces dense, high-resolution features rather than sentences. Meta’s model card lists 12 checkpoints, from a 21M-parameter ViT-S to the 6.7B ViT-7B plus four ConvNeXt models, and says simple linear layers on top of the frozen features are enough for classification, segmentation, depth estimation and video tracking.
Two details make DINOv3 relevant to VLM builders. First, its features are strong at the pixel level, which is exactly where caption-trained encoders tend to blur. Meta reports DINOv3 matches or beats SigLIP 2 and Perception Encoder on many classification benchmarks while “drastically” widening the gap on dense tasks. Second, the DINOv3 repository ships dino.txt, a text encoder aligned to a distilled ViT-L for zero-shot, open-vocabulary segmentation. In practice, teams use DINO as the eyes of a system and attach a lightweight head, an MLP projector, or a separate language model when they need words out.
Key capabilities and use cases
- Documents and OCR: reading forms, tables, charts and handwriting. Gemma 4, Qwen3.8 and InternVL3.5 all list document parsing as a core skill.
- Grounding and detection: pointing to or boxing an object a user describes. Ai2’s Molmo 2 extends pointing and tracking to multi-image and video.
- Video understanding: Qwen3.8-27B advertises hour-scale video; Google says Gemini 4 Argon scores 91.7% on the LVBench long-video test, per its launch post.
- Screen and GUI agents: reading a desktop or phone screen and acting on it. Qwen reports 84.3 on OSWorld-Verified for Qwen3.8-27B, and OpenAI’s GPT-6.2 Sol supports a computer use tool.
- Dense visual features: segmentation, depth and change detection, the home turf of DINOv3.
The capability matrix
The table below compares ten widely used options as of November 2026. Every cell comes from the developer’s own model card, documentation or announcement, linked in the model name. Figures describe what vendors publish, not independent testing.
| Model | Developer | Type | Parameter sizes | Open weights / license | Inputs | Key strengths | Context or resolution note | Best fit |
|---|---|---|---|---|---|---|---|---|
| Gemma 4 | Google DeepMind | Full VLM (12B is encoder-free) | E2B, E4B, 12B, 26B A4B (MoE), 31B | Yes, Apache 2.0 | Image, interleaved multi-image, video as frames (up to 60 s); audio on E2B, E4B, 12B | OCR, document and PDF parsing, charts, UI, object detection, pointing, reasoning | 128K (small) or 256K (medium) tokens; image budgets of 70 to 1,120 tokens | On-device and self-hosted assistants |
| PaliGemma 2 | Full VLM (fine-tune base) | 3B, 10B, 28B (SigLIP plus Gemma 2) | Yes, Gemma Terms of Use | Image, short video captioning | Captioning, VQA, text reading, detection, segmentation | 224 and 448 px variants benchmarked; single-turn, not a chatbot | Narrow tasks you plan to fine-tune | |
| DINOv3 | Meta AI (FAIR) | Vision encoder (self-supervised backbone) | ViT 21M to 6.7B; ConvNeXt 29M to 198M | Yes, DINOv3 License (commercial use, gated download) | Image; video via frame features | Dense features: segmentation, depth, detection, tracking, retrieval; dino.txt adds zero-shot text alignment | Patch size 16; any image size in multiples of 16; generates no text | Backbone for custom vision pipelines, satellite and specialist imagery |
| Llama 4 (Scout, Maverick) | Meta | Full VLM (native early fusion, MoE) | 17B active: 109B total (Scout), 400B total (Maverick) | Yes, Llama 4 Community License | Text and image; tested up to 5 images | Visual recognition, image reasoning, captioning, charts and documents | 10M tokens (Scout), 1M (Maverick) | Long-context self-hosting on large GPUs |
| Qwen3.8-27B | Alibaba Qwen | Full VLM (LM with vision encoder) | 27B dense | Yes, Apache 2.0 | Image, video (hour-scale) | Documents, STEM diagrams, computer and GUI agents, reasoning | 262,144 tokens native, extensible to 1M | Open agentic multimodal work on one server |
| InternVL3.5 | OpenGVLab | Full VLM (ViT, MLP, LLM) | 1B to 241B (MoE, 28B active) | Yes, Apache 2.0 | Image, multi-image, video | OCR, charts, documents, grounding, GUI and embodied tasks | Dynamic high resolution; 256 visual tokens per tile (64 in Flash) | Choosing an exact size for your hardware |
| Molmo 2 | Ai2 | Full VLM | 4B, 8B, 7B (fully open Olmo variant) | Yes, Apache 2.0 (research and education use; data terms apply) | Image, multi-image, video | Pointing, counting, object tracking, video grounding | Open training data and code | Research and transparent video grounding |
| Gemini 4 (Neon, Hydrogen, Carbon) | Full multimodal model | Not disclosed | No, API only | Text, images, audio, video, PDFs | Long video, PDFs and documents, computer use, Search grounding | 1M unified tokens | Managed enterprise multimodal workloads | |
| GPT-6.2 Sol | OpenAI | Full VLM (image input, text output) | Not disclosed | No, API only | Text and image (no audio or video) | Reasoning over images, tool use including computer use | 1,050,000-token context; 128K max output | API agents that read screenshots and documents |
| Claude Opus 5.5 | Anthropic | Full VLM (image input, text output) | Not disclosed | No, API only | Text and image | Vision with reasoning and tool use for knowledge work | 1M tokens; 128K max output | Document-heavy knowledge work via API |
How to choose
Open or closed. Open weights let you run the model in your own data center, keep images on premises and fine-tune on your data. Closed APIs such as Gemini 4, GPT-6.2 Sol and Claude Opus 5.5 trade that control for frontier capability and zero hosting work; none of the three vendors discloses parameter counts.
Size and the edge. If the model must live on a phone, laptop or camera, look at Gemma 4 E2B and E4B, InternVL3.5 at 1B to 4B, Molmo 2 at 4B, or a small DINOv3 ConvNeXt backbone. Mixture-of-experts models such as Gemma 4 26B A4B activate only about 3.8B parameters per token, which Google says lets it run “almost as fast as a 4B-parameter model.”
Licensing. Read the license before the benchmark table. Apache 2.0 (Gemma 4, Qwen3.8-27B, InternVL3.5) is the most permissive. The Llama 4 Community License requires a separate license from Meta for companies above 700 million monthly active users and asks for “Built with Llama” attribution. DINOv3 uses Meta’s own commercial license with gated downloads. Molmo 2’s weights are Apache 2.0, but Ai2 notes it was trained on third-party datasets subject to academic and non-commercial terms, per the Molmo 2 card.
Generate or perceive. If you need answers in words, choose a full VLM. If you need masks, measurements or embeddings at scale, a frozen encoder like DINOv3 plus a small head is usually cheaper and easier to validate.
What it means for business, IT and healthcare
For business leaders, VLMs turn image-heavy back-office work, from claims photos to shipping labels, into structured data without bespoke computer-vision projects. For IT teams, the decisive questions are where images are processed, how many visual tokens each request burns, and whether the license allows the intended use. InternVL3.5’s decoupled deployment, which runs the vision encoder and language model on separate GPUs, shows how serving architecture is now part of the cost conversation, per its technical report.
Healthcare organizations are watching closely, and vendors are publishing medical benchmarks. Google reports Gemma 4 31B at 61.3% on the multimodal MedXPertQA test, and PaliGemma 2’s card includes results on MIMIC-CXR chest X-ray report generation. Meta notes that DINOv2 already underpins research in histology, endoscopy and medical imaging. These are research benchmarks, not clinical validation or regulatory clearance, so any deployment still requires local evaluation, privacy review and clinical governance.
Conclusion
The VLM market no longer has one right answer. Frontier APIs lead on long video and complex reasoning, open families like Gemma 4, Qwen3.8 and InternVL3.5 bring strong document and agent skills under permissive licenses, Molmo 2 offers unusual transparency, and DINOv3 remains the go-to set of eyes for teams building their own pipelines. Start with the task, the data rules and the license, then let the matrix narrow the shortlist to two or three models worth testing on your own images.
Sources
- Gemma 4 model card, Google DeepMind
- PaliGemma 2 model card, Google
- DINOv3: Self-supervised learning for vision at unprecedented scale, Meta AI
- DINOv3 model card (ViT-L/16), Meta AI on Hugging Face
- DINOv3 reference implementation and models, GitHub
- Llama 4 Scout model card, Meta on Hugging Face
- Qwen3.8-27B model card, Qwen on Hugging Face
- InternVL3.5-8B model card, OpenGVLab on Hugging Face
- InternVL3.5: Advancing Open-Source Multimodal Models, arXiv
- Molmo2-8B model card, Ai2 on Hugging Face
- Latest Gemini models, Gemini API documentation
- Gemini 4 Argon: our next era of frontier intelligence, Google
- GPT-6.2 Sol model page, OpenAI API documentation
- Models overview, Claude Platform documentation